Apple SiliconAvailable
M1 – M4 · Metal
Veizik for Apple Silicon →Use-cases drawn from what the engine does today — server, on-device, edge, multimodal and control. Each is marked Verified, Supported or On the roadmap, from the ledgers, never from a promise.
One native engine on NVIDIA CUDA, Ampere through Blackwell. The checkpoint you downloaded is the one it runs — no Python environment on the box, no converted model copy, no framework stack to patch.
The engine is a compiled binary. It reads the published weights and executes them natively — nothing to pip-install and nothing to keep in sync.
Generation happens on your own hardware. Prompts, weights and outputs stay on the machine; only account, activation and downloads reach the network.
Every performance figure on the site is taken on named hardware with a released binary, bound to that build’s checksum.
Veizik for NVIDIA → NVIDIA results → Download →
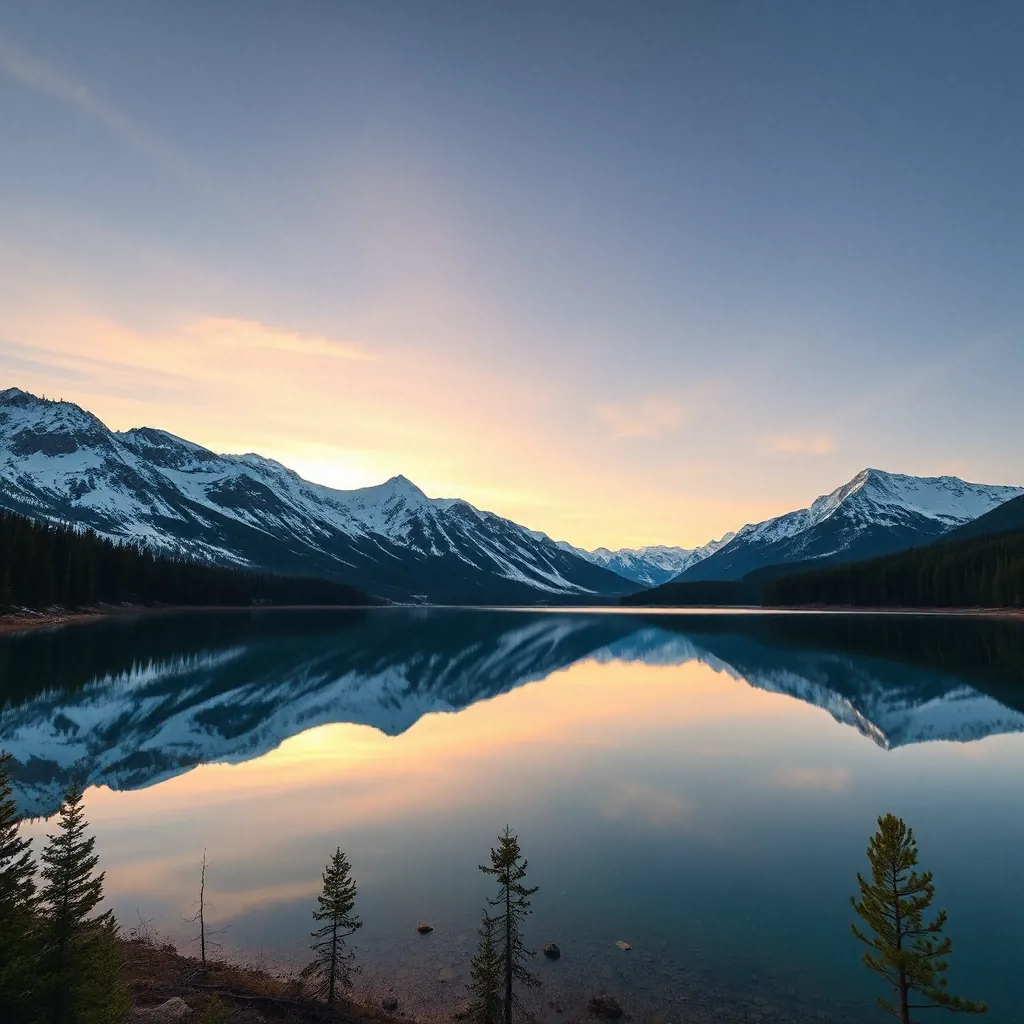
Drawn natively by Veizik on an NVIDIA RTX 3090 — FLUX.1-schnell output, not a benchmark.
Language models run on Apple Silicon today, M1 through M4, as one Metal binary. On Android edge SoCs the engine is measured on the board and deployment is still pending — shown as roadmap, not as shipped.
M1 – M4 · Metal
Veizik for Apple Silicon →On-device Android · measured on the board
Edge & mobile hardware →The engine is pure-native and dependency-free, so it runs on CPU edge boards — Raspberry Pi 5 and Zero 2 W — with no accelerator required. Language, on-device vision, image and video run on the board.
Veizik on the edge → SoC hardware → Edge models →
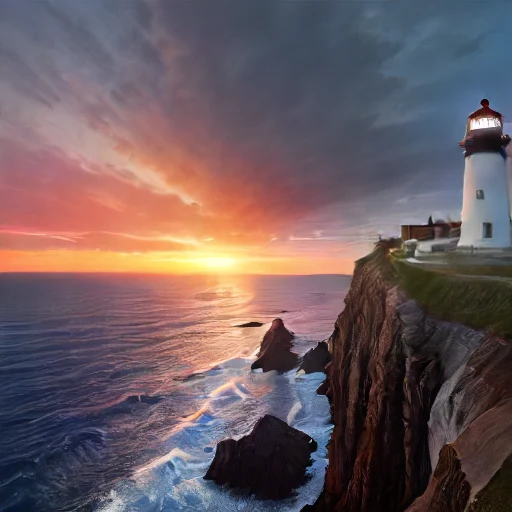
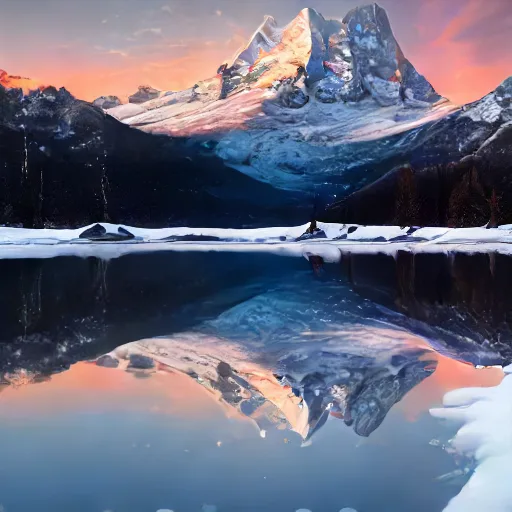
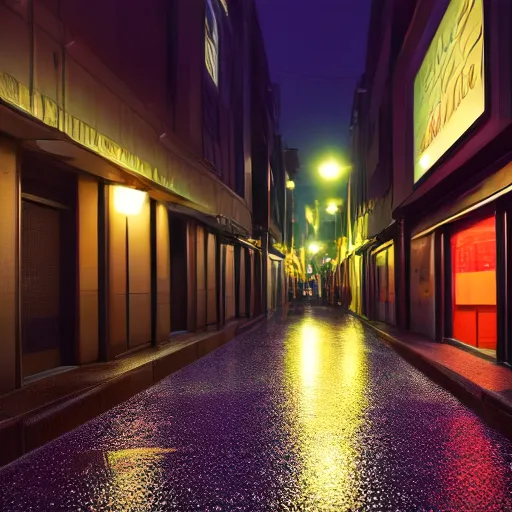
Shown as what the engine draws on the board — output, not a benchmark. Each was rendered by Veizik natively on a Raspberry Pi, with no accelerator.
The same engine runs large and small language models, text-to-image and image-to-image, and text-to-video and image-to-video. One install, one command surface, one set of licence rules — across every class it supports.
Reinforcement-learning control policies run as native on-device engines. These are the four policies that ship with their weights and are verified on hardware; Jetson control policies are on the roadmap.
The control policies are distributed with their weights (Stable-Baselines3 RL Zoo, MIT) — install and run, no separate download.
A control step is reproducible on the shipped build, the same discipline every published figure is held to.
Jetson AGX Orin is a render-proven preview for generative models; Jetson control policies are on the roadmap and marked as such.
Activation binds a licence to each machine, the engine ships sealed and hardened, and generation stays on your hardware. Fleet-scale controls are in active development and are shown as roadmap, not as shipped.
Security & licensing → Licensing → Talk to us about deployment →
Everything above runs from the same install. Start with your hardware, or read how the engine works.