Ease of use
From a prompt to a video, in one session.
What the product feels like to use: a four-command start, and three models — language, image and video — chained on one engine. The measured end-to-end timing follows; the shape and the output are here now.
AI-generated · the chain’s output — WAN 2.2 i2v
AI-generated · Powered by Wan-AI/Alibaba · the final stage of the chain below
Four commands to a render
Install, activate, pull, run.
After the one-time download, your first render is one command.
1
veizik install fluxFetch the model engine and verify its SHA-256. One package.
2
veizik activateApprove this machine once; the licence binds to the device.
3
veizik pull flux1schnellFetch the checkpoint into the local cache, ready to run.
4
veizik run flux1schnell "a lighthouse at dawn"Generate once and exit — your first render.
One session, three models
Language writes it, image draws it, video moves it.
The cross-modal chain on one engine, counted end-to-end.
- One session, three models. A language model writes a prompt, an image model draws it, and WAN 2.2 image-to-video animates the still — language, image and video on the same native engine, switched without leaving the session.
- The whole chain on one timeline. The schedule below counts every part — the model switch, the load and the render at each stage — as one continuous run, so the number is the experience, not a best-case for one step.
- The live, fastest run is coming. The measured end-to-end timing — with the fastest path on the hypercache build — is being prepared; this page carries the shape of the chain and its output now, and the figures follow.
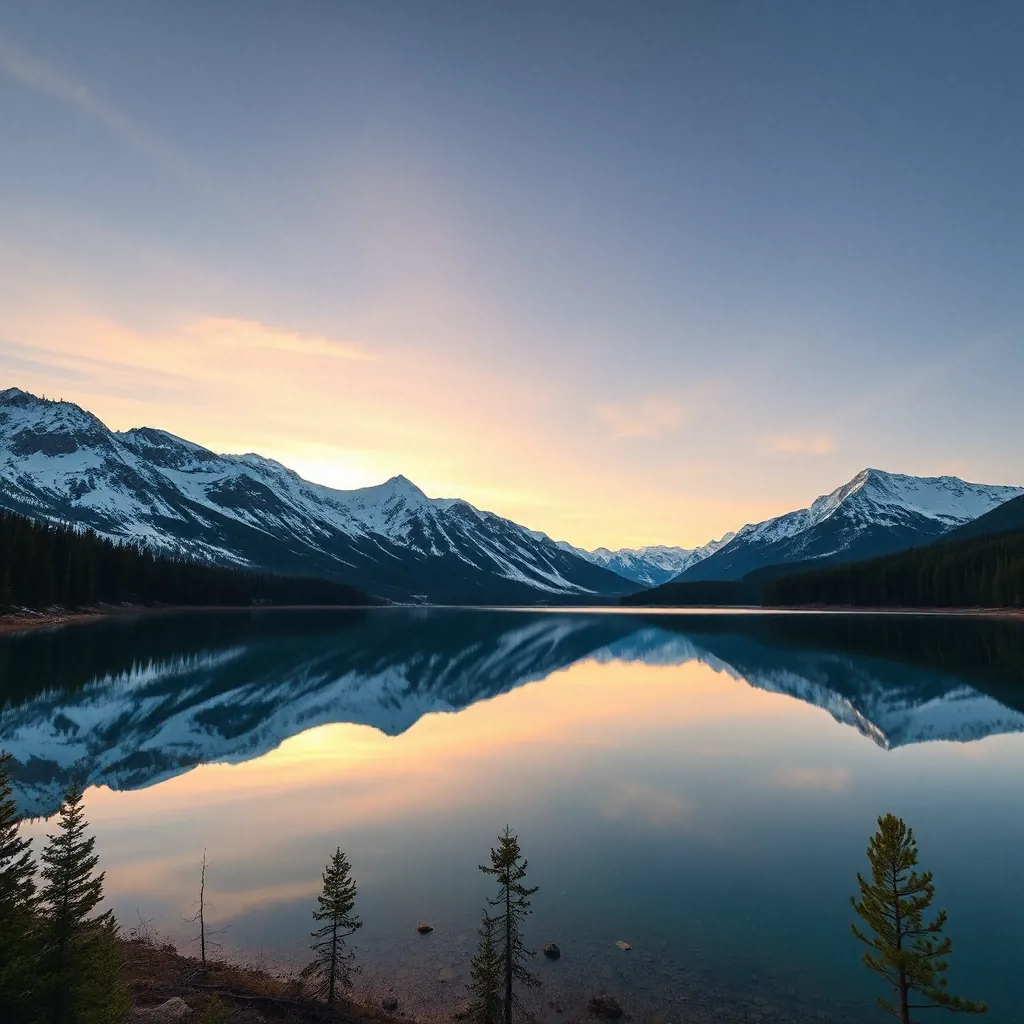
The image stage, shown: FLUX.1-schnell drawn natively by Veizik on an RTX 3090 — output, not a benchmark.